Introduction
PostgreSQL Streaming Replication is a widely used high-availability and disaster recovery (DR) solution that continuously transfers Write-Ahead Log (WAL) records from a primary PostgreSQL server to one or more standby servers. This helps maintain a synchronized copy of the database and supports recovery in the event of a primary server failure.
In this guide, we will configure PostgreSQL streaming replication between two servers running Red Hat Enterprise Linux (RHEL) or Oracle Linux. The configuration covers the primary database setup, standby initialization, replication parameters, and basic monitoring commands.
Prerequisites
Before starting, ensure that the following requirements are met:
- PostgreSQL is installed on both primary and standby servers.
- Both servers use compatible PostgreSQL versions.
- Network connectivity is available between the servers.
- The PostgreSQL port (default:
5432) is accessible between the two servers. - The PostgreSQL operating system user has the required permissions.
- Sufficient disk space is available for the database cluster and WAL files.
Example Environment
| Component | Primary Server | Standby Server |
|---|---|---|
| Role | Primary | Standby |
| IP address | 192.168.56.170 | 192.168.56.171 |
| PostgreSQL port | 5432 | 5432 |
| Data directory | /var/lib/pgsql/16/data | /var/lib/pgsql/16/data |
| Replication user | replication | replication |
Note: Replace the example IP addresses, PostgreSQL version, port, and data directory with the values used in your environment.
Step 1: Install PostgreSQL on Both Servers
Install PostgreSQL on both the primary and standby servers using the appropriate PostgreSQL repository and package management commands for your Linux distribution.Linux downloads
For example, on RHEL or Oracle Linux with PostgreSQL 16 packages available:
dnf install -y postgresql16-server postgresql16Initialize the database cluster on the primary server:
/usr/pgsql-16/bin/initdb -D /var/lib/pgsql/16/dataIf the data directory has already been initialized, do not run initdb again.
Important: The standby server will receive its initial database copy from the primary using pg_basebackup. Do not initialize a separate database cluster on the standby if you intend to use the base backup procedure below.
Step 2: Create a Replication User
Connect to the primary database as a PostgreSQL administrator:
sudo -u postgres psqlCreate a dedicated replication user:
CREATE ROLE replication
WITH REPLICATION
LOGIN
PASSWORD 'StrongPasswordHere';
Verify that the user has replication privileges:
SELECT rolname, rolreplication, rolcanlogin
FROM pg_roles
WHERE rolname = 'replication';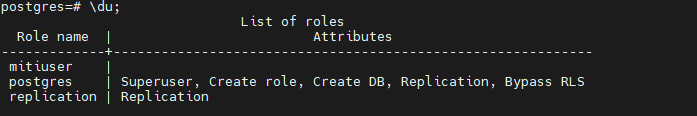
The replication role must be able to log in and initiate replication connections.
The same PostgreSQL role does not need to be created independently on the standby for physical streaming replication because the standby uses the primary server’s replication account for its connection.
Step 3: Configure Authentication on the Primary Server
Edit the primary server’s pg_hba.conf file, usually located in:
/var/lib/pgsql/16/data/pg_hba.confAdd an entry allowing the standby server to connect for replication:
# TYPE  DATABASE      USER          ADDRESS             METHOD
host    replication   replication   192.168.56.171/32   scram-sha-256
If your environment uses a different authentication method, configure it consistently with the password encryption settings and security requirements.
For older installations using MD5 authentication, the following form may be appropriate:
host replication all 0.0.0.0/0 trustUse the narrowest possible network range instead of allowing access from all addresses.
Reload the primary PostgreSQL configuration after making the changes:
SELECT pg_reload_conf();Alternatively:
sudo systemctl reload postgresql-16Ensure the primary server’s firewall allows incoming PostgreSQL connections from the standby server.
Step 4: Configure Streaming Replication Parameters on the Primary
Edit the primary server’s postgresql.conf file:
vi /var/lib/pgsql/16/data/postgresql.confConfigure the following parameters:
listen_addresses = '*'
port = 5432

wal_level = replica
max_wal_senders = 10
max_replication_slots = 5
primary_conninfo = 'user=postgres host=192.168.56.170 port=5432 sslmode=prefer /sslcompression=0 gssencmode=prefer krbsrvname=postgres target_session_attrs=any'

wal_keep_size = '1GB'
archive_mode = on
archive_command = 'test ! -f /path_to/archive/%f && cp %p /path_to/archive/%f'
Parameter descriptions:
listen_addresses: Allows PostgreSQL to listen on the required network interfaces.wal_level = replica: Enables the WAL information required for physical streaming replication.max_wal_senders: Sets the maximum number of concurrent WAL sender processes.max_replication_slots: Allows PostgreSQL to maintain replication slots.wal_keep_size: Retains a minimum amount of recent WAL data to help standby servers catch up.archive_mode: Enables WAL archiving.archive_command: Copies completed WAL files to the configured archive directory.
Create the archive directory and assign suitable ownership and permissions if WAL archiving is enabled:
mkdir -p /path_to/archive
chown postgres:postgres /path_to/archive
chmod 700 /path_to/archive
Replace /path_to/archive with an actual directory that has adequate storage capacity.
Version note: Older PostgreSQL versions used wal_keep_segments. In PostgreSQL 13 and later, use wal_keep_size instead. PostgreSQL 12 and later also use standby.signal rather than recovery.conf to indicate standby operation.
Step 5: Start the Primary PostgreSQL Server
Start PostgreSQL on the primary server:
systemctl enable --now postgresql-16Check the service status:
systemctl status postgresql-16Verify that PostgreSQL is listening on the configured port:
ss -lntp | grep 5432Connect to the database and confirm that it is operating as the primary:
SELECT pg_is_in_recovery();Expected result:
f
A result of false indicates that the server is not in recovery and is operating as a primary.
Step 6: Prepare the Standby Data Directory
Before creating the standby, ensure that the standby PostgreSQL service is stopped:
systemctl stop postgresql-16Warning: The following procedure deletes the existing contents of the standby data directory. Confirm the path and ensure that no required database files are present before proceeding.
For a new or intentionally reinitialized standby, clear the existing data directory:
rm -rf /var/lib/pgsql/16/data/*Run this command only on the standby server, never on the primary.
Ensure that the data directory exists and has the correct ownership:
mkdir -p /var/lib/pgsql/16/data
chown postgres:postgres /var/lib/pgsql/16/data
chmod 700 /var/lib/pgsql/16/data
Step 7: Copy the Primary Database Using pg_basebackup
Run pg_basebackup on the standby server to create a consistent copy of the primary database.
Execute the command as the PostgreSQL operating system user:
sudo -u postgres /usr/pgsql-16/bin/pg_basebackup \
  -h 192.168.56.170 \
  -p 5432 \
  -D /u01/datadir \
  -U replication \
  -P -v \
  -R \
  -X stream \
  -C \
  -S standby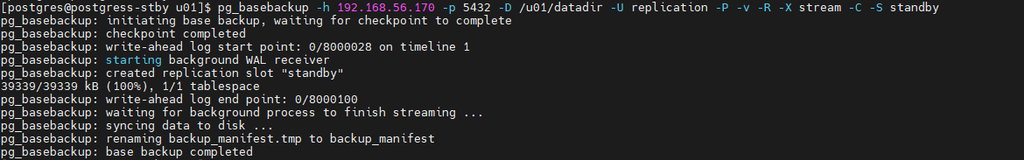
Command options:
-h: Primary server IP address.-p: Primary PostgreSQL port.-D: Destination data directory on the standby.-U: Replication user.-P: Displays backup progress.-v: Enables verbose output.-R: Automatically creates standby configuration.-X stream: Streams the WAL required during the base backup.-C: Creates a replication slot.-S standby: Names the replication slotstandby.
The primary server must have enough available WAL sender processes, and the replication user must have the required privileges.
When prompted, enter the replication user’s password. For automated environments, use a protected .pgpass file rather than exposing passwords in shell history or scripts.
For PostgreSQL 12 and later, pg_basebackup -R creates the standby configuration file standby.signal and records the connection settings in postgresql.auto.conf. Therefore, a separate recovery.conf file is not required.
Step 8: Configure the Standby Server
After pg_basebackup completes successfully, review the standby configuration.
For PostgreSQL 12 and later, confirm that the following file exists:
ls -l /var/lib/pgsql/16/data/standby.signalReview the generated connection settings:
grep -E 'primary_conninfo|primary_slot_name' \
  /var/lib/pgsql/16/data/postgresql.auto.conf
The generated configuration should contain the equivalent of:
primary_conninfo = 'host=192.168.56.170 port=5432 user=replication'
primary_slot_name = 'standby'
These settings are illustrative; retain the values generated by pg_basebackup -R and ensure the required authentication method is configured.
Enable read-only queries on the standby if needed by setting the following parameter in postgresql.conf:
hot_standby = onhot_standby enables read-only queries during recovery. It does not enable replication by itself.
Legacy PostgreSQL Versions
For PostgreSQL 11 and earlier, standby configuration uses recovery.conf. A legacy configuration may include:
standby_mode = 'on'
primary_conninfo = 'host=192.168.56.170 port=5432 user=replication password=StrongPasswordHere'
trigger_file = '/var/lib/pgsql/trigger'
This is for older releases only. Do not use recovery.conf or standby_mode in PostgreSQL 12 and later. For modern versions, use standby.signal and the configuration generated by pg_basebackup -R.
Step 9: Start PostgreSQL on the Standby Server
Start the standby service:
systemctl enable --now postgresql-16Check the service status:
systemctl status postgresql-16If the service fails, review the logs:
journalctl -u postgresql-16 -n 100 --no-pagerConfirm that the standby is operating in recovery mode:
SELECT pg_is_in_recovery();Expected result:
t
A result of true confirms that the database is in recovery mode, as expected for a standby server.
Step 10: Monitor PostgreSQL Streaming Replication
Once the standby server starts successfully, verify that the primary and standby are communicating.
Check the Primary Server
Connect to the primary database and execute:
SELECT
    pid,
    usename,
    application_name,
    client_addr,
    state,
    sync_state,
    sent_lsn,
    write_lsn,
    flush_lsn,
    replay_lsn
FROM pg_stat_replication;
This query displays the connected standby servers and their replication status.
Important columns include:
client_addr: IP address of the standby.state: Replication connection state, normallystreamingwhen healthy.sync_state: Synchronous replication status.sent_lsn,write_lsn,flush_lsn, andreplay_lsn: WAL progress positions.
If the query returns no rows, investigate connectivity, authentication, standby startup, and replication configuration.
Check the Standby Server
Connect to the standby database and run:
SELECT
    pg_is_in_recovery(),
    pg_last_wal_receive_lsn(),
    pg_last_wal_replay_lsn(),
    pg_last_xact_replay_timestamp();
These values help determine whether WAL is being received and replayed.
To inspect the receiver process:
SELECT *
FROM pg_stat_wal_receiver;
You can also check the operating system processes:
Primary server:
ps -ef | grep '[w]al sender'Standby server:
ps -ef | grep '[w]al receiver'The process names and monitoring views may vary by PostgreSQL version.
Step 11: Test Replication
To verify that replication works, create a test table on the primary database:
CREATE TABLE replication_test (
    id integer PRIMARY KEY,
    message text,
    created_at timestamp DEFAULT current_timestamp
);

INSERT INTO replication_test (id, message)
VALUES (1, 'Streaming replication test successful');
Connect to the standby and query the table:
SELECT * FROM replication_test;The inserted row should appear after the WAL changes have been replayed on the standby.
Remember that physical streaming replication makes the standby read-only during normal recovery. Perform data modifications on the primary, not on the standby.
Troubleshooting Common Issues
1. Replication Connection Fails
Check the following:
- The primary server is running and listening on the correct port.
- The standby IP address is allowed in
pg_hba.conf. - The replication username and password are correct.
- Network and firewall rules permit communication on port
5432.
2. Standby Does Not Start
Review the PostgreSQL service logs:
journalctl -u postgresql-16 -n 100 --no-pagerConfirm that the data directory has the correct ownership, the base backup completed successfully, and the configuration matches the installed PostgreSQL version.
3. Replication Lag Increases
On the primary, inspect pg_stat_replication. On the standby, inspect pg_stat_wal_receiver and the WAL receive/replay positions.
Possible causes include network latency, heavy database workload, slow storage, insufficient WAL retention, or standby replay delays.
4. Replication Slot Retains Excessive WAL
Replication slots protect WAL needed by connected or temporarily disconnected standbys. However, a stalled standby can cause substantial WAL accumulation.
Monitor slot status on the primary:
SELECT
    slot_name,
    slot_type,
    active,
    restart_lsn,
    wal_status
FROM pg_replication_slots;
The wal_status column is available in PostgreSQL 13 and later. Investigate inactive slots and retained WAL carefully before making changes.
5. WAL Archive Command Fails
Check the archive directory’s existence, permissions, free disk space, and PostgreSQL log messages. Ensure the archive command returns success only after a WAL file has been archived successfully.
Important Production Considerations
Before using streaming replication in a production environment, consider the following:
- High availability: Streaming replication alone does not automatically promote the standby when the primary fails. Configure a controlled failover process or an appropriate HA solution.
- Replication slots: Monitor retained WAL to prevent disk exhaustion.
- Backups: Maintain independent, tested database backups. Replication is not a substitute for backup because accidental deletions and logical changes can propagate to the standby.
- Monitoring: Track replication lag, connection state, WAL retention, disk utilization, and archive failures.
- Security: Use strong passwords, restrictive network access, and appropriate authentication.
- Version compatibility: Use the correct parameters and procedures for your PostgreSQL version.
- Failover testing: Test promotion, application reconnection, and standby reinitialization before relying on the configuration for disaster recovery.
Conclusion
PostgreSQL Streaming Replication provides a practical foundation for database high availability and disaster recovery by continuously transferring WAL records from a primary server to a standby server.
By configuring authentication, enabling WAL streaming, initializing the standby with pg_basebackup, and monitoring replication status, database administrators can establish a reliable replication environment on RHEL or Oracle Linux.
For production deployments, combine streaming replication with tested backups, monitoring, and a documented failover and recovery procedure to improve database resilience.